- trackaffadmin
- 0 Comments
- 26 Views
Incrementality testing measures the conversions Meta ads caused, not the conversions they simply touched. For most performance teams, the right move is to use Meta’s built-in Conversion Lift for campaign-level checks, and reserve a properly powered geo or user-level holdout for bigger budget decisions. Trust the result only when it comes from a randomized holdout backed by a real power analysis.
TL;DR:
- Meta’s incrementality testing isolates conversions that truly result from ads, filtering out overlaps and overlaps that inflate attribution metrics.
- Conversion Lift, user holdouts, and geo tests are suited for different audience sizes, channels, and offline impacts, with geo tests best for broader business-level insights.
- Ensuring tests are properly powered with correct minimum detectable effect thresholds and aligned measurement windows is crucial for credible results.
- Clean conversion data, including off-site events, improves lift estimates, making tools like Trackaff essential for reducing noise and increasing accuracy.
- Relying solely on Meta’s modeled attribution without experimental validation risks misjudging true incrementality, especially for definitive budget or strategic decisions.
Table of Contents
- What Incrementality Testing Measures (And Why Attribution Isn’t the Same Thing)
- Conversion Lift, User Holdouts, and Geo Tests: Picking the Right Method
- Designing a Test That Actually Holds Up to Scrutiny
- Reading Meta’s Results and Turning Them Into a Budget Decision
- Why Meta Incrementality Tests Fail, and How to Fix Them
- How Cleaner Conversion Data Tightens Your Lift Estimates
- When to Trust Meta’s Model and When to Run a Real Test
- Tighten Your Test Data Before You Trust Your Test Results
- Primary Sources and Implementation Guides
- Sources
- FAQ
What Incrementality Testing Measures (And Why Attribution Isn’t the Same Thing)
Attribution tells you which ad a converter saw last. Incrementality testing tells you whether that conversion would have happened anyway. The gap between the two is the whole reason this topic matters for anyone running real budget through Meta.
Incremental lift is the difference between what actually happened and what would have happened without the ad, a comparison researchers call the counterfactual. You can’t observe the counterfactual directly, so every credible method builds one artificially: a randomized holdout group, a matched geo market, or a synthetic control built from markets that never saw the campaign. A well-known example makes the stakes clear: one Universal App Campaign study found that suspending spend caused a statistically significant 6.57% drop in conversions. That’s the causal number. Everything Meta’s dashboard reports before that test runs is a proxy for it.
That proxy carries a cost some teams call the “attribution tax.” Meta’s pixel and Conversions API log conversions that happened after someone saw or clicked an ad, whether the ad influenced the decision or not. Someone who already had a browser tab open to check out still counts as an attributed conversion. This inflates platform-reported ROAS, sometimes substantially, because the model has no way to separate “the ad worked” from “this person was buying regardless.”
Meta’s own incremental attribution feature tries to close that gap without a full experiment. It’s a modeled, machine-learned estimate trained on historical lift-test data rather than a live randomized test on your account. That makes it fast and cheap to check, but it’s still Meta measuring Meta, and modeled estimates from the same platform selling the ads deserve a second opinion before you bet real budget on them.
What incrementality testing actually isolates:
- The portion of conversions that would not have happened without the campaign
- Whether reported ROAS reflects real revenue lift or overlapping demand
- Whether a channel deserves more budget, less budget, or a structural change in targeting
Statistic to remember: a 6.57% conversion drop from a spend-suspension test is a small number on paper, but at scale it separates real incremental revenue from noise that a standard attribution report would never flag.
Conversion Lift, User Holdouts, and Geo Tests: Picking the Right Method
Three methods dominate incrementality testing on Meta ads, and each answers a slightly different question.
- Meta Conversion Lift. This is Meta’s native randomized controlled test, built directly into Ads Manager. It splits your audience into exposed and holdout groups and reports lift percentage, incremental conversions, and confidence intervals once the test concludes. It works best when your audience is large enough to generate steady weekly conversions and you need a campaign-level answer quickly, without building custom infrastructure.
- User-level holdouts. You withhold a defined percentage of your audience from ad delivery and compare their conversion rate against the exposed group. This gives granular, individual-level data, but it’s vulnerable to contamination: holdout users who see your organic content, get retargeted through another channel, or convert through search after seeing the same product elsewhere. Overlapping audiences across campaigns make this worse.
- Geo holdouts and synthetic control (GeoLift). Instead of splitting users, you split markets. Some regions get the campaign, matched control regions don’t, and you compare aggregate outcomes. GeoLift, the open-source methodology from Meta, uses synthetic control techniques and ships with power calculators and model-fit diagnostics. Geo tests are the right call when you need a business-level answer that spans offline sales, cross-channel effects, or markets where user-level tracking is unreliable.
Choosing among the three comes down to three questions: How big is your addressable audience? Are you trying to measure Meta in isolation or Meta’s effect on total demand across channels? And how much contamination risk can you tolerate given your funnel? Small audiences with a single-channel funnel usually fit Conversion Lift. Multi-channel or offline-heavy businesses need geo-level answers because matched market pairs with strong pre-test correlation are the only reliable way to isolate Meta’s contribution from everything else happening at the same time.
Designing a Test That Actually Holds Up to Scrutiny
A test that isn’t powered to detect the lift you actually need to see is worse than no test at all. It produces a confident-looking null result that tells you nothing.
Start with the minimum detectable effect, or MDE. This is the smallest lift your test needs to reliably catch given your sample size, and it should be tied directly to a decision, not to wishful thinking. If a 5% lift wouldn’t change your budget allocation, don’t design a test that can only detect 15%. As one guide to designing defensible geo holdout tests puts it, you build the test around the minimum lift that would trigger a change, not the lift you’re hoping to see.
Power analysis inputs include your baseline conversion rate, its variance week to week, and your available sample size. High-variance conversion events (big-ticket purchases, long consideration cycles) need larger samples or longer runs to reach the same statistical confidence as a low-variance event like a newsletter signup.
A few operational benchmarks worth knowing:
- Platform Conversion Lift tests generally need 50 to 100+ weekly conversions per test cell and run 2 to 4 weeks.
- Holdout size typically ranges from 10% to 20% of your audience; go larger when you can afford the reduced reach, since bigger holdouts detect smaller effects.
- Test duration should span at least one full purchase cycle. A campaign selling a subscription with a 30 day consideration window needs a longer test than one selling an impulse purchase.
- Pre-treatment baseline data (ideally several weeks) confirms your test and control groups tracked together before the campaign started.
Lock your decision threshold before you launch. Agree in writing what lift percentage justifies scaling, what result means “no change,” and what triggers a pause. Freeze unrelated campaign changes during the test window, and check for audience overlap between your test and any other active campaign. This kind of upfront decision alignment is what separates a test people trust from one that gets relitigated the moment the number looks disappointing.
Pro Tip: Write your decision thresholds in a shared document before the test starts, and have every stakeholder sign off. Retroactively negotiating what counts as “significant” is how good tests get argued into meaninglessness.
Reading Meta’s Results and Turning Them Into a Budget Decision
Once a Conversion Lift test concludes, Ads Manager surfaces lift percentage, an estimated range of incremental conversions, and a confidence interval around both. Incremental Return on Ad Spend, or iROAS, divides incremental revenue (not total attributed revenue) by ad spend. That single substitution, incremental revenue instead of attributed revenue, is what makes iROAS a fundamentally different number from the ROAS on your standard dashboard.
Reading the result correctly matters more than running the test correctly:
- Positive, statistically significant lift: this is your green light to scale, but scale gradually and monitor whether lift holds as spend increases. Lift often decreases at higher spend because you’re reaching lower-intent audiences.
- Inconclusive result: this is not the same as “no effect.” An inconclusive result usually means the test was underpowered, the holdout was too small, or the duration was too short. Extend the test or increase the holdout before drawing any conclusion.
- Negative lift: investigate before you panic. Negative lift often points to contamination between test and control groups or a genuine performance problem, not necessarily proof the ads don’t work.
Triangulate rather than trusting Meta’s number in isolation. Export results to your data warehouse or CRM and compare them against other measurement checks. This matters because the gaps can be large: one analysis found Meta’s incremental attribution reporting an 87% incremental view against 67% from GA4, a 20 point spread on the same campaign. When your platform and your warehouse disagree by that much, the warehouse number, built on your own conversion data, deserves more weight.
Why Meta Incrementality Tests Fail, and How to Fix Them
Most disappointing test results trace back to one of four causes, and each has a fix.
- Contamination and spillover. Holdout users see organic posts, get retargeted by another campaign, or get exposed to overlapping audiences from a different ad set. Fix it by auditing audience overlap before launch and excluding any campaign that could reach your holdout group.
- Underpowering. A test with too few conversions or too small a holdout can’t detect the lift you’re looking for, producing an inconclusive result that gets misread as “the ads don’t work.” Fix it by running the power calculation before launch, not after you’re disappointed by the output.
- Cooldown window mismatches. If your measurement window is shorter than your customer’s typical decision cycle, you’ll cut the test off before the lift shows up. Align your window with your actual purchase cycle, and check post-treatment data for a few weeks past your official end date.
- Retargeting bias. Retargeting campaigns naturally reach people who were already close to converting, which inflates lift estimates if the holdout wasn’t built carefully around that same population.
Before trusting any result, check three diagnostics analysts rely on for geo experiments: pre-treatment parallel trends (did test and control markets move together before the campaign started?), the model’s fit metric such as L2 imbalance, and any suspiciously large negative lift, which almost always signals a data or setup problem rather than a real negative effect. The GeoLift analysis documentation walks through exactly these checks, including exportable fit plots and control weight files worth reviewing before you present a result to stakeholders.
Pro Tip: If a geo test comes back with unexplained negative lift, check your control market selection first. A poorly matched control market will manufacture a negative result out of nothing.
How Cleaner Conversion Data Tightens Your Lift Estimates
Every incrementality test is only as good as the conversion data feeding it. Standard Meta pixel tracking misses a meaningful share of off-site events, purchases completed after a page reload, deposits confirmed on a third-party payment page, registrations that finish outside the tracked funnel. Each missed conversion adds noise to your test data, widening your confidence intervals and making a real lift harder to detect statistically.
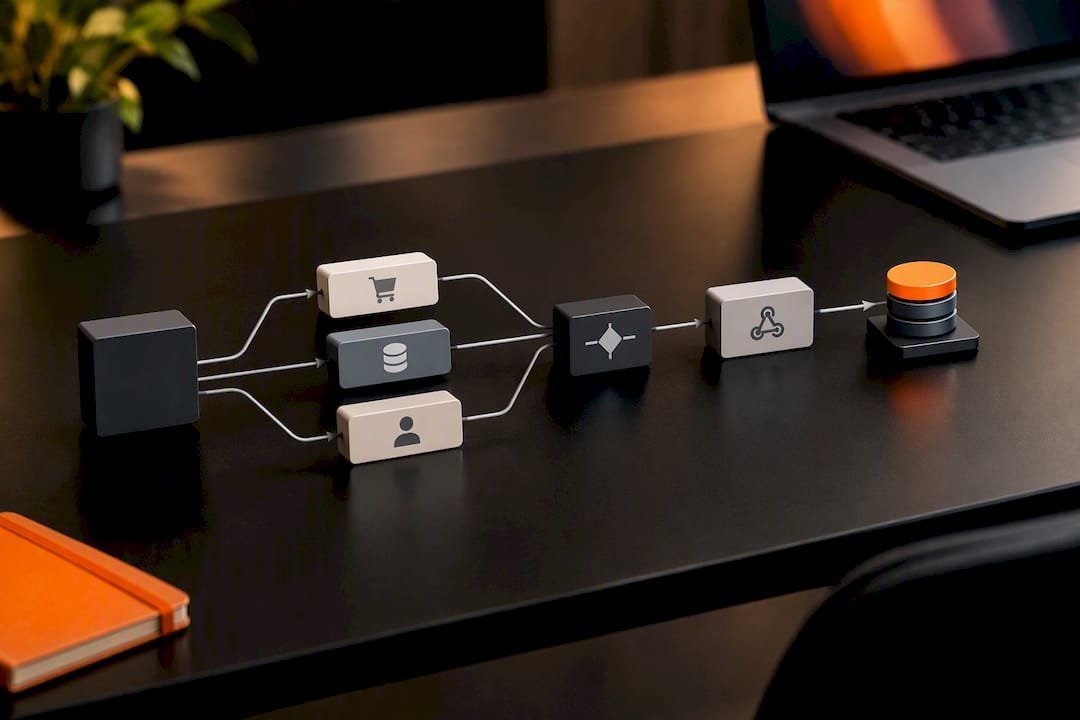
Trackaff addresses that gap directly. It uses a branded form integrated into the marketing funnel to capture post-click conversions, purchases, deposits, and registrations, and reports them back to Meta through the Conversions API. That means events your pixel would otherwise miss get counted where they belong: in the same dataset your Conversion Lift or geo test is analyzing. Add pixel and CAPI event deduplication plus CRM webhook support, and the practical effect is fewer missing conversions and narrower variance in your lift estimate, which makes iROAS calculations more reliable for the budget decision at the end of the test.
When to Trust Meta’s Model and When to Run a Real Test
The debate over modeled attribution versus experimental testing gets treated as a philosophical argument. It isn’t. It’s a practical question about the size of the decision in front of you.
Use Meta’s incremental attribution for what it’s built for: a fast, directional read for daily optimization. It’s cheap, it updates constantly, and it’s useful for catching obvious problems early. But don’t let a modeled estimate settle a six-figure budget reallocation or a decision to cut a channel entirely. That calls for a controlled experiment, Conversion Lift for a single-audience question, a geo holdout when cross-channel or offline effects are in play.
The strongest measurement stacks layer all three: attribution for daily pacing, incrementality experiments for causal proof on major decisions, and marketing mix modeling for cross-channel allocation over longer horizons. Treat each tool as answering a different question, not competing versions of the same answer.
— Terry
Tighten Your Test Data Before You Trust Your Test Results
Trackaff is the fix for the weakest link in most Meta incrementality tests: incomplete conversion data. Standard pixel tracking misses off-site purchases, deposits, and registrations that finish after the click, and every missing event widens your confidence interval and muddies your lift estimate.
Trackaff closes that gap with a branded form built into your funnel that captures post-click conversions and reports them back to Meta through the Conversions API, with CRM webhook support and pixel/CAPI deduplication so events aren’t double counted. That means the sales team, agency, or performance marketer running the test gets a cleaner conversion dataset without building custom server-side infrastructure from scratch. Cleaner inputs mean tighter confidence intervals and a more trustworthy iROAS number when the test concludes, whether you’re checking a single campaign or feeding a geo test.
Pricing runs by connected funnel: the Growth Rate plan at $69 per month per connection, Scale Rate at $49 per month per connection, or Starter Rate at $99 per month per connection, with Enterprise pricing available on request. Start a free trial and connect one funnel to see whether your current conversion capture is undercounting the events your next incrementality test depends on.
Primary Sources and Implementation Guides
Start with Meta’s own Conversion Lift documentation for platform-native setup, the GeoLift walkthrough for synthetic control methodology and power calculators, and the Amsive guide to defensible geo holdout design for translating MDE into a real decision threshold. For tying test outcomes back to marketing ROI, NULLBIT’s guide to digital marketing investment offers useful framing.
Sources
- GeoLift walkthrough (GitHub)
- Meta Ads incrementality testing
- Incrementality testing (LatentView glossary)
- Meta incremental attribution analysis (Stella)
FAQ
What’s the difference between A/B testing and incrementality testing?
A/B testing typically compares two ad variations to see which performs better among people who were exposed to an ad either way. Incrementality testing compares an exposed group against a true holdout that received no ad at all, which is what lets it measure causal lift rather than relative performance between two treatments.
How do you prove incrementality on Meta ads?
You prove it with a randomized holdout, either Meta’s native Conversion Lift test or a geo experiment using synthetic control methods like GeoLift. Both compare real outcomes against a constructed counterfactual, which is the only way to isolate what the ads actually caused versus what would have happened anyway.
Is A/B testing worth it on Facebook and Meta ads?
A/B testing creative or audience variants is useful for optimizing within a campaign, but it doesn’t answer whether the campaign caused incremental conversions at all. For that question, you need a holdout-based incrementality test rather than a standard A/B split.
How do you calculate incrementality?
Incremental lift is the difference between the conversion rate of an exposed group and a matched holdout or control group that saw no ads, usually expressed as a lift percentage. Incremental ROAS then divides incremental revenue, not total attributed revenue, by ad spend, giving a truer picture of what the campaign actually generated.
Does better conversion tracking improve incrementality test accuracy?
Yes. Missing off-site conversions add noise to both the exposed and holdout groups, which widens confidence intervals and makes real lift harder to detect. Tools like Trackaff that capture post-click purchases, deposits, and registrations and report them back to Meta reduce that missing-data problem and tighten the resulting lift estimate.
Recommended
Your deals close off the pixel. Meta never finds out.
TrackAff reports your real conversions back to Meta the moment they happen, tied to the exact ad that produced them. 10-minute setup, no code.
Start free 14-day trial → Card required · No charge until day 14 · Cancel in one click